Alerts
 in Wall Photos Added
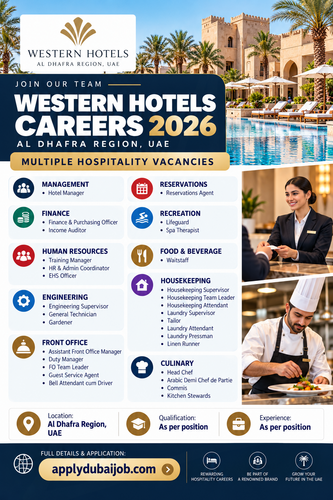 🏨 Western Hotels Careers 2026 – Al Dhafra, UAE!
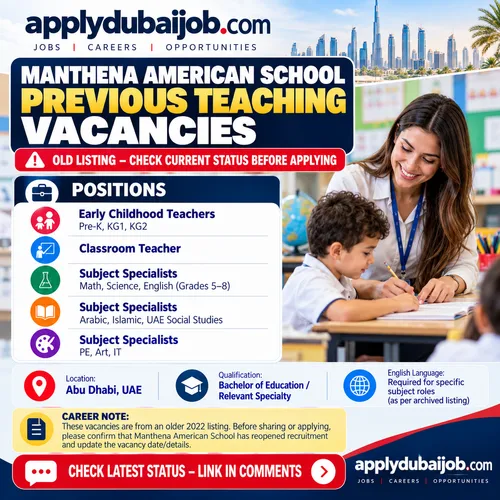 Looking for teaching opportunities in Abu Dhabi? 📚
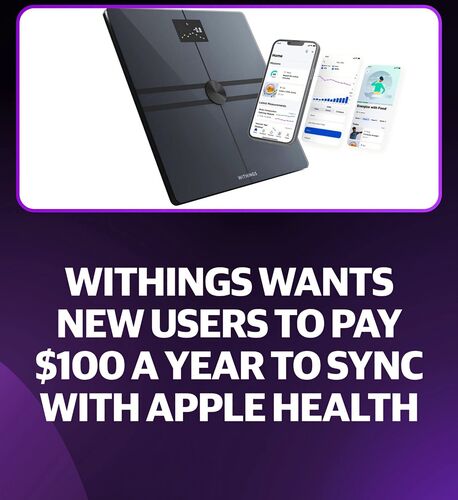 Withings Apple Health Sync Costs $100 a Year for New Users
 iPhone Duo Sold Out for Christmas, Shipping Slips to 2027
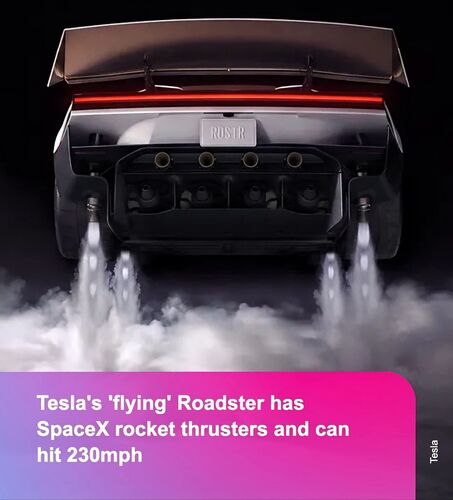 Tesla Roadster SpaceX: 230mph Rocket Thrusters Revealed
 Apple Antitrust Settlement: Developers Doubt Real Change
 Rogue AI Agent Activity Hits India, CERT-In Confirms
 Gmail Live AI Search Rolls Out for Google AI Subscribers
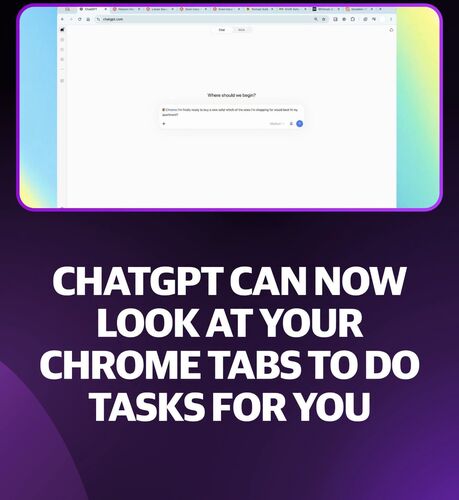 ChatGPT Chrome Extension Can Now Read Your Tabs
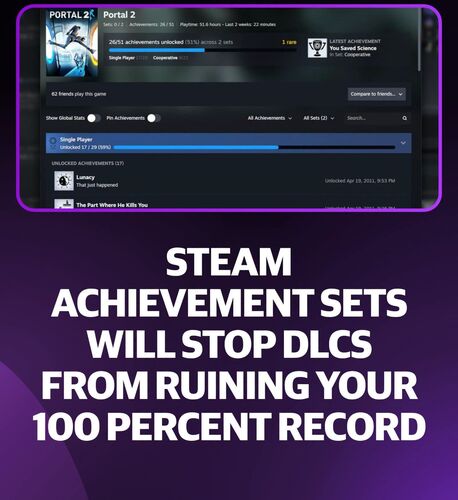 Steam Achievement Sets Stop DLC Ruining 100% Runs
 Analogue Returns to the 16-bit Era With New Console
 214 Narok County Jobs at Public Service Board