Alerts
-
3 minutes, 33 seconds
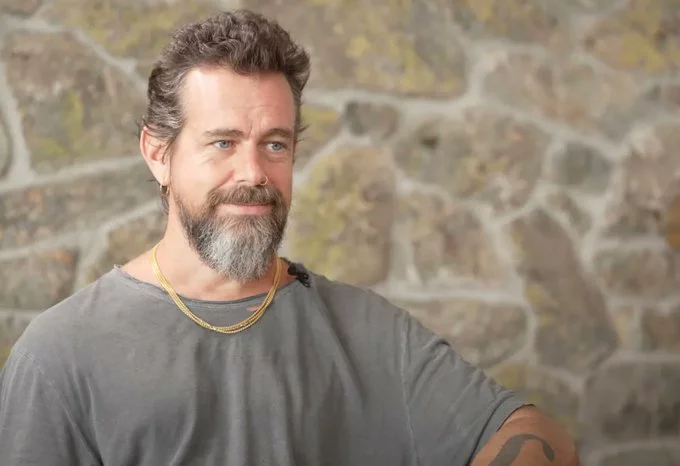
Block has released Dessa, a voice model developed by the company’s research lab. The model runs locally and is designed to sound strikingly human, with expressive details such as laughs, pauses and cries. Block says that Dessa was trained entirely on human speech using a single NVIDIA GPU rack.
Jack Dorsey described the model as a way to interact with intelligence through voice, calling conversation with Dessa similar to talking with a person. He pointed to its emotion, nuance, pauses and natural cadence. Those qualities give the model more than a smooth, uninterrupted speaking style: its delivery can include the small shifts in expression people use when they talk.
Dessa is also a full-duplex model, meaning it can listen and speak at the same time. Block presents it as a natural-sounding voice system, while noting that its knowledge comes from conversational data. Unlike typical speech models, which are paired with a large language model for knowledge retrieval, Dessa’s knowledge stems from the data used in conversation.
Block says Dessa was trained entirely on human speech, using a single NVIDIA GPU rack. That is the full extent of the training details the company shared: the source material was human speech, and the hardware was one GPU rack from NVIDIA. Block did not provide further specifics about the training process in its announcement.
The model runs locally, rather than relying on a remote service to produce its voice. Local operation is one of the details Block highlighted alongside Dessa’s human-sounding delivery, which includes expressions such as laughs, pauses and cries. The company released the model from its research lab.
These details describe both how Block says Dessa was built and how it operates: trained entirely on human speech with a single NVIDIA GPU rack, then run locally. Block has not specified in the source how much speech was used, how long training took, or what hardware configuration the rack contained. Its announcement also does not give further technical details about local deployment.
Dessa is a full-duplex voice model, meaning it can listen and speak simultaneously. That capability allows a conversation to unfold without the model having to wait for one person to finish speaking before it can respond. Block says Dessa works this way, much like OpenAI’s GPT-Live model, which the company released earlier in 2026.
Full-duplex operation is distinct from the typical setup in which a speech model is paired with a large language model for knowledge retrieval. Block says Dessa’s knowledge comes from its conversational data. The company has also described the model as being trained fully on human speech, and says it runs locally.
Block presents simultaneous listening and speaking as part of a more natural way to interact with intelligence. In its description, talking with Dessa feels like talking with a person, with emotion, nuance, pauses and a natural cadence. Its ability to listen while speaking supports that conversational style, rather than making the exchange feel like a sequence of separate voice commands and replies.
Speech models are typically paired with a large language model to retrieve knowledge. Block says Dessa works differently: its knowledge comes from the conversational data used to train it. That makes the source of its knowledge part of the model’s speech training, rather than a separate large language model paired with it for retrieval.
The company says Dessa was trained fully on human speech, and describes its knowledge as stemming from the conversational data it has. The source does not specify what topics that data covers, how much conversational data the model was trained on, or whether it can retrieve information from outside that data. It does, however, set out a contrast with the usual pairing of speech models and large language models: Block attributes Dessa’s knowledge to conversational data.
That distinction sits alongside the model’s focus on natural conversation. Block says talking with Dessa feels like talking with a person, with emotion, nuance, pauses, and a natural cadence. Its conversational training data is also the basis Block identifies for what the model knows.



Comment